Table of contents
AINewsTracker turns financial news into records that can be searched, analysed and compared with market data.
The project is a FastAPI service with separate routes for news, articles, companies, users, data seeding and trading strategies. Routes receive HTTP requests; services and repositories handle analysis and storage.
1. From a feed to an article
A news request starts a collection job. The news service retrieves feed content and creates article records. The metrics service analyses the text, and the article repository stores the result in MongoDB.
| Responsibility | Source file |
|---|---|
| Receive the request | app/routers/news.py |
| Collect news | app/core/services/news.py |
| Analyse the text | app/core/services/metrics.py |
| Store articles | app/core/repo/article.py |
Routes describe the API surface, models define stored data, services perform the news work, and repositories isolate database access. app/main.py also configures Redis caching.
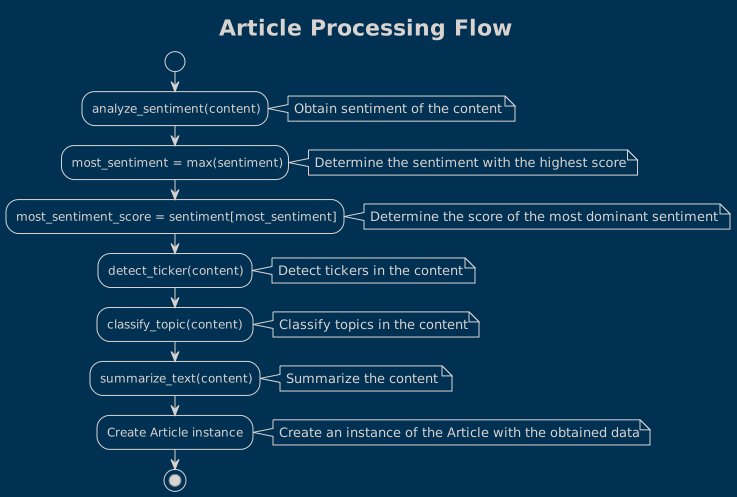
AlgoETS. (2026, November 5). Article processing flow. AINewsTracker repository, docs/diagrams/out/article_processing_flow.svg.
Original processing diagram[1].

2. Keep the source attached to the analysis
The documentation’s data overview[2] connects four records: a news source produces articles, comments belong to an article, and company records identify the businesses it mentions. Source metadata includes language and country. Articles retain their URL, publication date and text alongside analysis fields.
That separation makes a result easier to inspect. A sentiment label can be traced to an article and its publisher. A company’s ticker provides a way to connect mentions across articles without treating every spelling of its name as a different business.
3. What the text analysis produces
The documented NLP outputs include a sentiment label and score, ticker detections, a summary and topic labels. These fields answer different reading questions: which company is discussed, what the article says, and how its language is classified. The documentation’s sample records illustrate the model; the Pydantic classes define the actual fields.
I would inspect the original text beside those outputs before using them as strategy inputs. A summary can omit a condition, and a company mention does not establish that the article concerns a tradable event. The source URL and publication date therefore belong in the review path.
4. Analysis and backtesting
The project documentation describes sentiment analysis, topic classification, ticker allocation and article summarisation. The strategy route sends backtest requests to app/core/trading/strategy.py.
These labels are inputs to an experiment. They do not prove that a news item caused a market move, and a historical backtest does not guarantee future performance.
A useful review separates the data stages:
| Stage | What to inspect |
|---|---|
| Collection | Publisher, source URL, publication time and retrieved text |
| Text analysis | Detected companies, labels and summary against the original article |
| Strategy input | Which observations were available at the point being tested |
| Backtest output | The chosen period, assumptions and the strategy’s reported result |
This review checks the data available to the strategy, its assumptions and its reported result. The article presents no measured prediction accuracy or trading returns.
5. Read the architecture
The complete GitDiagram includes route registrations, models, repositories, seeders, MongoDB, Redis and the trading branch. Each node links to its source file.